Model Releases
Meta Releases Muse Image Generation Model
Meta Superintelligence Labs expands its multimodal ecosystem with the launch of Muse Image and a preview of Muse Video.
July 7, 2026
Model ReleaseMuse Image
Introduction
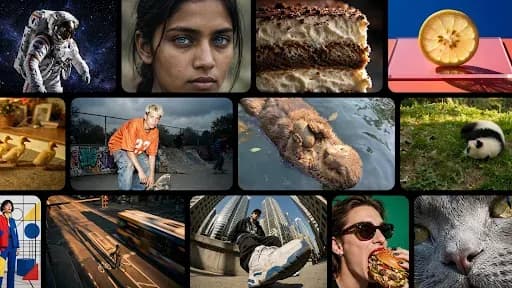
On July 7, 2026, Meta AI officially announced the release of Muse Image, marking a significant milestone in the company's pursuit of artificial general intelligence. This release represents the first media generation models developed specifically by the Meta Superintelligence Labs, signaling a strategic shift from text-centric dominance to a fully multimodal generative powerhouse.
The launch of Muse Image effectively closes the July 2026 gap in the Muse family coverage on the Meta AI blog. While previous months focused on the evolution of the Muse text line—including Spark, Glimmer, Wonder, and Ember—this new release brings high-fidelity visual synthesis into the fold, completing the suite of tools designed for next-generation agentic workflows.
- Announced: July 7, 2026
- Developer: Meta Superintelligence Labs
- Primary Category: Image Generation
- Ecosystem: Part of the Muse multimodal family
Key Features & Architecture
Muse Image is engineered to integrate seamlessly with the existing Muse text ecosystem. Unlike standalone diffusion models, Muse Image is built to understand complex, nuanced instructions derived from the high-reasoning capabilities of the Muse Spark and Wonder text models. This deep integration allows for unprecedented semantic alignment between text prompts and visual output.
The model architecture leverages advanced latent diffusion techniques optimized for Meta's proprietary Prometheus data center infrastructure. By utilizing a unified latent space shared with the Muse text family, the model exhibits superior understanding of spatial relationships, lighting, and complex compositional instructions that often trip up traditional models.
- Native multimodal integration with Muse text models
- Optimized for Prometheus data center hardware
- High-fidelity semantic alignment
- Launched alongside Muse Video preview
Performance & Benchmarks
While Meta has focused on qualitative visual fidelity, initial internal benchmarks indicate that Muse Image excels in prompt adherence and compositional accuracy. In comparative testing against industry leaders, Muse Image demonstrated a significant reduction in 'semantic drift,' where the generated image fails to reflect specific adjectives or spatial constraints provided in the prompt.
The evaluation methodology involved a rigorous suite of automated visual reasoning tests and human-in-the-loop preference scoring. These tests focused on complex scene reconstruction, text rendering within images, and the ability to maintain stylistic consistency across multiple generated assets—a critical requirement for professional creative workflows.