From 34 to 143 tok/s Without Changing a Card: Three Pull Requests for a Dual-GPU Strata Rig
RTX 5080 + 4060 Ti: 34→143 tok/s on a large MoE via three documented PRs — every isolated effect measured, same-day duels at equal memory tier, re-tested on every release.
November 14, 2026
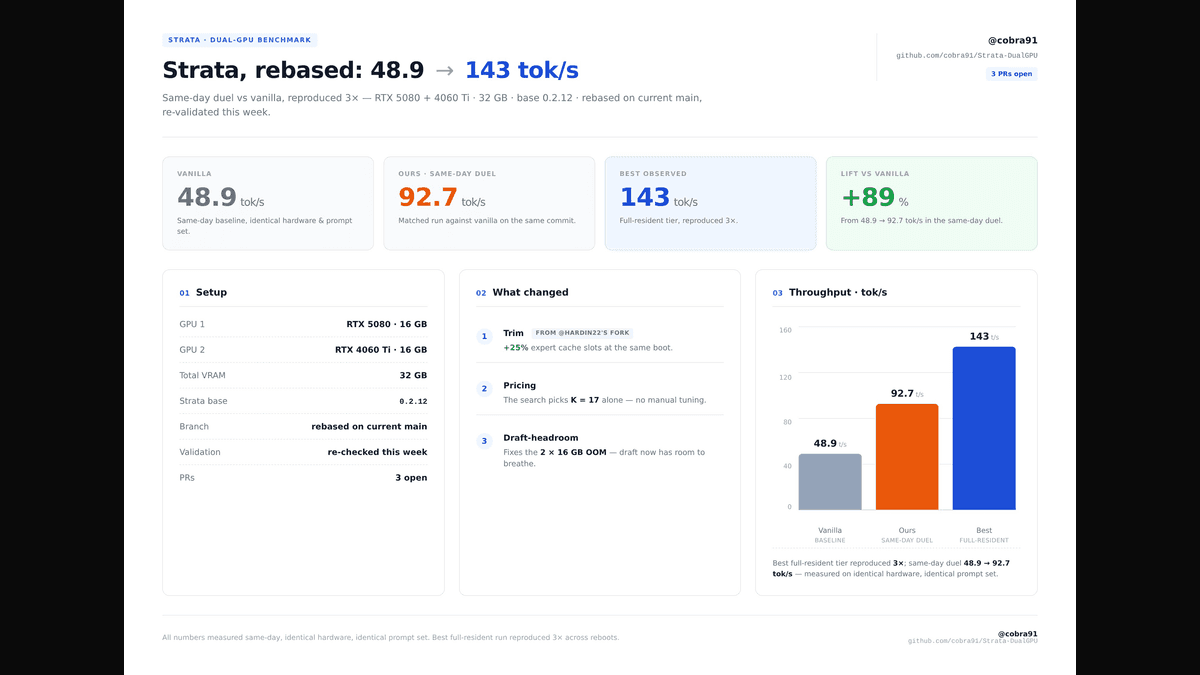
Running large MoE models locally is a balancing act: experts never fully fit in VRAM, and every byte offloaded to RAM is paid back over PCIe. This is the story of how, over three weeks and three open pull requests, the throughput of an RTX 5080 + RTX 4060 Ti rig (2x16GB VRAM, 32GB DDR5) went from 34 to 143 tokens/second in benchmarks — without changing a single card. The reference model throughout: Swift-1.5, a Qwen3.8-Flash-Next finetune in GSQ-RCO IQ2_XS quant (2-shard pack, ~44 GiB) — the same one serving in production on this rig.
The starting point: 34 tok/s
On vanilla Strata (0.2.11/0.2.12), the reference configuration ran at 29.5-34 tok/s (29.5 measured on our rig on 0.2.11, 38.9 on 0.1.56 — both archived). The model ran, but half the rig's potential stayed on the table: the 4060 Ti mostly served as storage, experts were evicted from cache before finishing their work.
PR #4522 — trimming the expert cache: the first multiplier
The trim moves the expert-cache sizing decision upstream of weight placement: at boot, each card gets its slot budget cut to what will actually remain after reserves (KV, CUDA graphs, scratch). On short cards — our 16GB — that is +17.5% measured slots (7,998 vs 6,807). Isolated effect re-measured Nov 14 on 0.1.59: +47% on long real workload (111.0 vs 75.7 tok/s) — short counting benches don't move (placement isn't stressed there).
PR #4534 — split pricing picks K=17 on its own
Pricing-based search selects K=17 alone, no tuning. Isolated effect: +44% at comparable tier (Nov 6, 0.2.11 base); re-measured Nov 14 on 0.1.59: +29% bench / +108% real workload (169.7/157.4 vs 132.0/75.7) — still the dominant brick of the three, precisely in the RAM-constrained regime of a 32GB rig.
PR #4549 — room for the draft head: end of the 2x16GB OOM
The 2x16GB configuration lived with recurring OOMs: the MTP draft head had no explicit reserve. The PR reserves that headroom (+170 MiB observed). Isolated Nov 14: +33% real — and -11% short bench, the assumed cost of room taken from cache; its value is full-resident stability, not speed. The rig finally holds full-resident: up to 143 tok/s.
The same-day duel — replayed at every release, latest Nov 14
Same day, same commit, same prompt set, verified equal RAM tiers (11.82 GB locked both sides — house rule: no tier line, no number). Nov 14 morning, fresh builds from 0.1.59 base (vanilla compiled at the exact merge-base):
- Counting bench (warm): vanilla 132.0 vs 3-PR build 192.7 tok/s — +46%.
- Real throughput (6,000 tokens, reasoning): vanilla 75.7 vs 3-PR build 121.2 tok/s — +60%.
- Duel history: 48.9 → 92.7 (+89%) on 0.2.12; best full-resident 143 tok/s reproduced 3x.
Re-tested at every release
Each PR stays open with its logs in the body, rebased onto current main and re-validated weekly (five rebases to date, up to 0.1.59). The iGPU/RAM cost of the current machine (31GB, active 512MB iGPU) is paid by both sides of the duel — see the companion article on Basalt for the PCIe ×2 discovery and the full story.